Near-Future Parkour Run in 3D Toon Anime Style
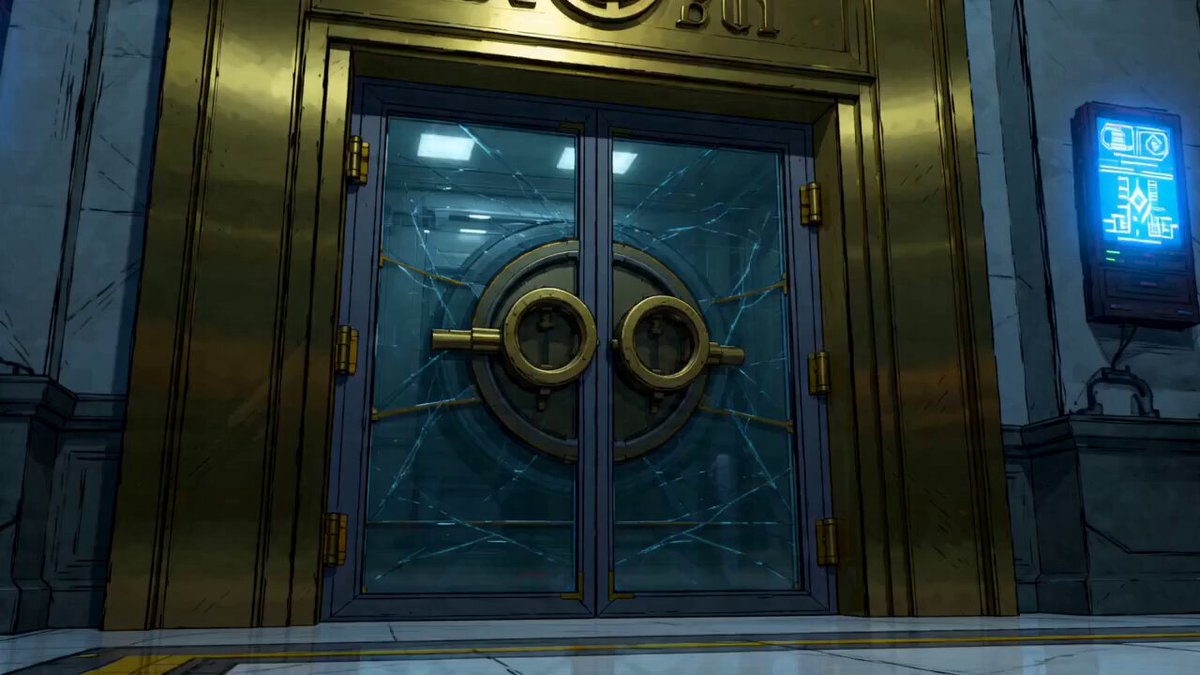
A continuous, uninterrupted parkour sequence through a dense near-future city, rendered in high-density 3D toon/cel-shaded anime style. The prompt locks a single character's face, hair, outfit, and silhouette to reference images while allowing only natural secondary motion in hair and clothing. It emphasizes theatrical-grade 3D character animation, layered cel shadows, and detailed urban backgrounds.
Prompt
How to use this prompt ▾
- Copy the prompt using the green "Copy prompt" button above.
- Open your model — launch Seedance 2.0 on its official interface.
- Paste & generate — keep the verbatim prompt text for best adherence. Set aspect ratio to 16:9 and clip duration to 4s.
Related cases
Browse all video prompts →


What makes this prompt work
Every insight below is verified against benchmark generation parameters, not asserted. How our prompt engineering benchmarks work →
- CAMERA
- "handheld" is a core cinematic camera technique for establishing spatial immersion and subject framing. Also present: "tracking".
- LIGHTING
- "silhouette, cinematic lighting" establishes luminance depth, volumetric shadow falloff, and tonal contrast across the generation.
- MOOD
- "energetic, cinematic" — Mood and aesthetic tone are explicitly directed to maintain emotional consistency throughout the scene.
- DURATION
- At 4s, this clip is optimized for high temporal coherence and fluid, realistic motion physics.
- MODEL
- Seedance 2.0 (ByteDance) provides the underlying diffusion and motion architecture. Camera, lighting and duration cues transfer across models — what differs is how literally each model interprets motion.
- PROMPT LANGUAGE
- The prompt is written in Chinese. This library keeps every prompt in its original language rather than translating it — the exact words are what was conditioned during generation.
Seedance 2.5 BytePlus Cloud Partner
Tell bigger stories with Seedance 2.5
Create AI videos up to 30 seconds long with richer image, video, and audio references. Ideal for complex ideas that need consistency and control.
Explore on BytePlus Official ByteDance Enterprise Cloud